

Out of respect for my readers’ time, let me say it right away: no, the era of AGI (Artificial General Intelligence) has not arrived yet. The current progress of LLMs (such as GPT-6 or Fable-5.1) is impressive, but it remains limited to domains with known rules, where the outcome can be easily judged as either right or wrong. For IT and business leaders, this is an important takeaway about where to apply AI. The fundamental architectural decision now concerns which processes, systems and operational decisions we can design so that AI works within them effectively, predictably and safely.
What is AGI?
AGI, or Artificial General Intelligence, means an artificial intelligence system capable of solving a broad range of problems across various contexts, without the need to design a separate solution for every task.
Do we already have AGI, and how do we recognize it?
AGI, or Artificial General Intelligence, means an artificial intelligence system capable of solving a broad range of problems across various contexts, without the need to design a separate solution for every task. There is no full consensus on exactly what characteristics an AGI system must possess to be genuinely named a general intelligence. One popular test, similar to the Turing Test and attributed to Steve Wozniak, is the coffee test. According to its premise, an AGI should be able to walk into an unknown room, with unfamiliar equipment (a coffee machine), and be able to make a cup of coffee. It is certainly an interesting test, showing that achieving AGI requires progress in physical AI.
If we look only at LLMs, the latest models such as GPT-6 Astra or Claude Fable 5.1 have achieved remarkable results in tasks performed within a well-defined environment, where the outcome can be judged objectively as correct or incorrect. A good example of a “stable” environment is generating source code or solving mathematical problems. In such areas, we are indeed seeing enormous progress. LLMs, however, are less performant within tasks in chaotic or highly complex environments, such as financial markets analysis (where share prices are shaped by company fundamentals, macroeconomic trends, the psychology of individual investors and of those running large funds, and so on).
Table: LLM effectiveness across ordered and complex environments
| Type of environment | Characteristics of tasks | Examples | Effectiveness of LLMs |
| Ordered | Well defined rules, easy and unambiguous assessment of the outcome (correct/incorrect). | Generating source code, solving mathematical problems. | Very high (enormous progress). |
| Complex (chaotic) | Many variables (fundamentals, macroeconomics, psychology), no uniform rules, discovering cause-effect relationships. | Financial market analysis, epidemiology and public health. | Moderate (models perform significantly worse). |
To understand where this effect comes from, we need to answer the question…
Why are LLMs so good at solving mathematical problems?
Let us travel back in time exactly ten years. In March 2016 we witnessed an event, that astonished the scientific community working on AI and changed how the technology was viewed across Asia. I am referring to the match between AlphaGo, developed by DeepMind, and Lee Sedol, a grandmaster of Go. AlphaGo won that match 4:1. Across Asia, 200 million people followed this event live, making it a major social phenomenon.
To understand how today’s LLMs are trained, let us first look at how AlphaGo was built:
- Supervised learning: In the initial phase the model was trained on real matches played by humans. In this way it acquired knowledge of the basic rules and strategies.
- Reinforcement learning: Two models were put against each other. The outcome (a win or a loss) was used as a reward or a penalty, which allowed the model to improve continuously.
- Continuous iteration and scaling: Thanks to round-the-clock training over many days, the model was able to discover entirely new strategies previously unknown to humans.
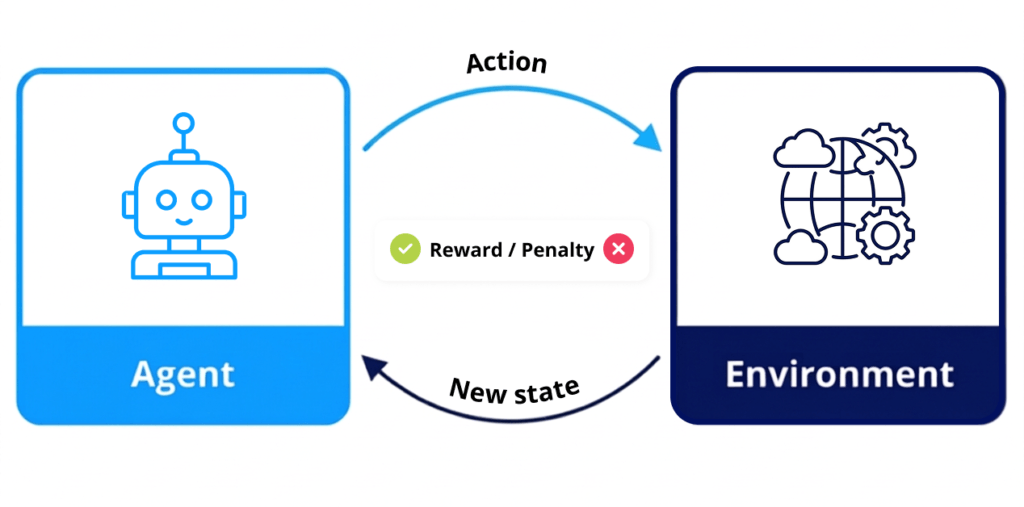
A similar mechanism lies behind the rapid development of Large Language Models today. Their training process is complex and multi-stage, but an important breakthrough was thdevelopment of AI reasoning models, which rely precisely on reinforcement learning (specifically Reinforcement Learning with Verifiable Rewards). Because models “talk” to themselves during training and are able to evaluate the outcomes and we can run this process constantly, we see a new model each month. Also, the nature of reinforcement training enables LLMs to become excellent in domains where that outcome is easy to judge as right or wrong and the rules are known in advance (just as in a game). Such domains include math, but also – and perhaps above all – generating source code or using a computer.
So what does this mean for business?
The conclusion is simple: when planning AI applications and deployments in an organization, it is worth focusing on making the fullest possible use of the technology in well-structured areas, that is, those in which the outcome is relatively easy to assess. It is precisely in these areas that current and future generations of AI models will keep getting better.
It is difficult today to point to a single, universally applicable list of specific generative AI use cases. I am convinced, however, that the most significant area of AI application will be corporate IT and data analytics. Here are my arguments:
- First, writing source code or scripts that support business operations takes place within rigid rules (the grammar of the programming language, compilation, the program’s runtime environment).
- Second, it is possible to immediately assess the outcomes (syntax checks, compilers, unit tests).
- Third, the programs themselves have an enormous impact on how organizations operate and how effective they are.
Mapping those areas is easier with a structured view of where the technology actually pays off, which is what our Big AI Framework sets out.
For enterprise architects, one useful pointer is that AI will most likely keep getting better at operating the computer itself and at completing tasks using the tools provided to it (programs and scripts).
This is the practical starting point for AI enterprise architecture: the boundary of what the model is allowed to touch matters more than the model itself.
Agentic AI in enterprise systems: how much autonomy to grant
The main design decisions concerning AI will therefore revolve around the trade-off between predictability of results (a large set of tools with well-understood behavior, narrow and tightly defined AI agent actions) and dynamic adaptation to external conditions (more autonomy and fewer predefined tools).
The AGI era may not have arrived yet. But the era of systematically designing organizations for the effective use of AI has already begun. And it is CIOs who will be among the principal architects of that change. The first question on that path is rarely which model to use. It is whether the organization is ready to build on AI at all.
FAQ
Has AGI (Artificial General Intelligence) already been achieved?
No. Today’s models perform extremely well inside environments with known rules and verifiable outcomes, and much less well in chaotic ones such as financial market analysis. The coffee test makes the gap concrete: a general intelligence should be able to enter an unfamiliar room and make a cup of coffee on equipment it has never seen. That requires progress in physical AI, not only in language models.
What is the difference between AGI and AI?
AGI describes a system able to solve a broad range of problems across different contexts without a separate solution being designed for each task. What we have today is narrower. It is very strong in well-defined domains, and its strength comes from how those domains can be scored as correct or incorrect during training. The distinction matters for planning, because it tells you which processes are realistic candidates for AI today and which are not.
Why are LLMs better at math and coding than at complex real-world problems?
Because of how they are trained. Reasoning models rely on reinforcement learning with verifiable rewards, the same principle that took AlphaGo past human grandmasters: the model tries, the outcome is scored, and the process runs continuously. Code and mathematics fit that loop, since compilers, syntax checks and unit tests give an immediate verdict. Financial markets or epidemiology give no such clean signal, so the training advantage disappears.
What does the rise of AI mean for enterprise IT strategy?
The practical implication is to concentrate on areas where the outcome is easy to assess, because those are the areas where each new model generation keeps improving. Corporate IT and data analytics sit at the centre of that. Code runs within rigid rules, its correctness can be checked immediately, and it shapes how the whole organization operates. That combination is rare elsewhere in the business.
Should CIOs design systems around narrow, predictable AI tasks or more autonomous AI agents? This is the core trade-off. A large set of tools with well-understood behaviour and tightly defined agent actions gives predictable results. More autonomy and fewer predefined tools give better adaptation to changing conditions, at the cost of predictability. There is no single correct answer, but the decision should follow from how well the outcome of a given task can be verified. Where verification is cheap and fast, autonomy is easier to justify.
Would you like more information about this topic?
Complete the form below.